Wednesday, February 3, 2016

Improve content assist for xml in Eclipse

The default configuration for xml content assist doen't feel very convenient for real usage.When you change you maven pom.xml or maybe the spring xml-style config files, the eclipse doesn't give you much help automatically. To get assist you need to keep pressing Ctrl+Space.

Here is a simple tip to improve the user experience for editing XML files, by making auto-trigger for assist more often. Window->preferences, set

<=:. _abcdefghijklmnopqrstuvwxyz like below. (There's a space among this string, before '_').

image

This can help you work more smoothly with XML files in Eclipse.

Monday, February 1, 2016

Quick overview of Maven plugin configuration

This article tries to give a quick generic overview of Maven plugins. In the end a pluginin usage is given and explained, so you can get a feeling of how maven plugins look like as a whole.  plugins refer to maven plugins in the following context.

1. Plugin naming rules

The naming convention for official plugins is maven-<plugin name>-plugin. For example, maven-surefire-plugin

The recommand third-party and user-defined plugin should be named <plugin name>-maven-plugin.  For example the plugin for spring boot is named spring-boot-maven-plugin

2. Plugins type

Build plugins will be executed during the build and they should be configured in the <build/> element from the POM. 
Reporting plugins will be executed during the site generation and they should be configured in the <reporting/> element from the POM.

Build plugins  ( <build/>) are more common to see.

3. Available plugins list

Here is the complete availble plugins from official, you can also find a plugin is a build plugin or a report plugin or both on that page.

4. Plugin goal

A plugin goal represents a specific task (finer than a build phase) which contributes to the building and managing of a project. It may be bound to zero or more build phases.

If a goal is bound to one or more build phases, that goal will be called in all those phases automatically.  For example if a plugin has goal bound to phase 'package', then when run 'mvn package' that plugin's goal will be executed.

A goal not bound to any build phase could be executed outside of the build lifecycle by direct invocation.

#============================================================================
# Syntax for invoke a plugin's goal from command line:
# mvn <plugin name>:<goal> [-D<plugin name>.<property name>=<property value>]
#============================================================================
#For example, use 'exec' plugin, goal is 'java', set the plugin property of 'mainClass'
mvn exec:java -Dexec.mainClass="com.shengwang.demo.DemoMain"

All official plugins support a goal called 'help'. It has 2 properties 'detail' and 'goal'. See example below.

5. How to get available goals of a certain plugin.

  • Search keyword "maven <plugin name>  plugin" on google, jump to plugin's official web to learn how to use it. It's suitable for first time using a plugin.
  • In command line, run 'mvn <plugin name>:help', get all available goals. It's more convinient for experienced users for just missing some details.

For example here is the output of the 'mvn exec:help'

image

6. How to get more usage help from command line.

First run 'mvn <plugin name>:help' for all goals, then run 'mvn <plugin name>:help  -Ddetail=true -Dgoal=<goal>' for more usage details of a certain goal. You can try to run 'mvn exec:help -Dgoal=java -Ddetail=true' to see the output. (Don't forget the -D)

7. Basic configuration structure of plugins

For Build plugins, it's included in <build/>.  it has <executions/>, which is the real actiion that are intened to do during bounded build lifecycle.  Let's examine an example:

<build>
  <plugins>
  
    <!-- .... other plugins ...-->
  
    <!-- =========================================== -->
    <!-- make sure antrun is after packaging plugins -->
    <!-- =========================================== -->
    <plugin>
      <groupId>org.apache.maven.plugins</groupId>
      <artifactId>maven-antrun-plugin</artifactId>
      <version>1.8</version>
      <executions>
        <execution>
          <id>scp-to-remote</id>
          <phase>package</phase>
          <goals>
            <goal>run</goal>
          </goals>
          <configuration>
            <target>
              <!-- keyfile+passphrase or  password, choose one -->
              <!-- 
              <scp localFile="${project.basedir}/target/qos-spark-1.0.jar"
                remoteToFile="root@192.168.203.156:/usr/sanss" verbose="true"
                keyfile="C:\Users\shengw\.ssh\192.168.203.156\id_rsa"
                passphrase="">
              </scp>
               -->
              <scp localFile="${project.basedir}/target/qos-spark-1.0.jar"
                remoteToFile="root@192.168.203.156:/usr/sanss" verbose="true"
                password="passwordForSSH" trust="true">
              </scp>
            </target>
          </configuration>
        </execution>
      </executions>
      <!-- libraries for scp impl      -->
      <!-- antrun doesn't use os's scp -->
      <dependencies>
        <dependency>
          <groupId>com.jcraft</groupId>
          <artifactId>jsch</artifactId>
          <version>0.1.53</version>
        </dependency>
        <dependency>
          <groupId>ant</groupId>
          <artifactId>ant-jsch</artifactId>
          <version>1.6.5</version>
        </dependency>
      </dependencies>
    </plugin>
    <!-- =========================================== -->
    <!--   antrun plugin end                         -->
    <!-- =========================================== -->
  
  </plugins>
</build>

It's a long one, but no need to be panic. This example has the common configuration structure for maven plugins.  Most of the plugins' configuration are shorter.

It's included in <build/> because its a build plugin.

The first part of plugin configuration is trival:  <groupId>, <artifactId> and <version>.

Then there's one <execution> defined in above example. There are <id>, <phase>, <goal> and <configuration> in this <execution>. 

  • <id> - identify this execution. If more pom.xml  has the same plugin bound to same phase and has the same id, these <execution>  will be merged when building. Normally just give a meanful string for this execution.
  • <phase> - bind the execution to a build lifecycle. So it can get executed automatically at that build lifecycle. The above demo, executing antrun plugin when use 'mvn package'
  • <goal> - which behavior of this plugin to be used. In the example, the goal "run" will run some ant tasks. The tasks are defined in <configuration>.
  • <configuration> - Set property for the plugin. Normally any parameter in <configuration> has a corresponding field variable in the plugin class definition, just like a jave bean. For the <target> property, AntRunMojo.java from antrun plugin's source has the variable. Just treat the properties in <configuration> as setting values for these field variables.

image

If there are more <execution>, every one can has its own <configuration>. If <configuration> is out of <executions>, it's  for all <execution>.

Finally, <dependencies> in the <plugin>, to set external libraries only used for this plugin. Most plugins don't need to specify <dependencies> for plugin itself.

How to let maven copy(scp) created jar/war package to other location

In real development, you may found your development environment is different from the running environment. For example, like my own case,  I'm working on a Hadoop/Spark related project.  So I have all my source code and development environment like Eclipse/Maven setup on my Windows laptop, but maven created jar file has to be deployed to a linux  server in the lab with Spark installed. Maunally copy maven created jar file to remote server for every run is tedious, so I need to let maven automatically do the file upload when running command 'mvn package'.

The basic idea is to use a maven plugin called 'antrun', run a ant task at maven lifecycle 'package'. Ant has scp task to copy files locally or remotely.  By utilizing this scp task from ant, you can copy the created jar/war file to anywhere, such as to a different local directory or to a remote host.

The follow demo try to copy a jar file to a remote host.  All you need is to modify maven pom.xml file, add and config this antrun plugin.

1. pom.xml

<build>
  <plugins>
  
    <!-- .... other plugins ...-->
  
    <!-- =========================================== -->
    <!-- make sure antrun is after packaging plugins -->
    <!-- =========================================== -->
    <plugin>
      <groupId>org.apache.maven.plugins</groupId>
      <artifactId>maven-antrun-plugin</artifactId>
      <version>1.8</version>
      <executions>
        <execution>
          <id>scp-to-remote</id>
          <phase>package</phase>
          <goals>
            <goal>run</goal>
          </goals>
          <configuration>
            <target>
              <!-- keyfile+passphrase or  password, choose one -->
              <!-- 
              <scp localFile="${project.basedir}/target/qos-spark-1.0.jar"
                remoteToFile="root@192.168.203.156:/usr/sanss" verbose="true"
                keyfile="C:\Users\shengw\.ssh\192.168.203.156\id_rsa"
                passphrase="">
              </scp>
               -->
              <scp localFile="${project.basedir}/target/qos-spark-1.0.jar"
                remoteToFile="root@192.168.203.156:/usr/sanss" verbose="true"
                password="mypassword" trust="true">
              </scp>
            </target>
          </configuration>
        </execution>
      </executions>
      <!-- libraries for scp impl      -->
      <!-- antrun doesn't use os's scp -->
      <dependencies>
        <dependency>
          <groupId>com.jcraft</groupId>
          <artifactId>jsch</artifactId>
          <version>0.1.53</version>
        </dependency>
        <dependency>
          <groupId>ant</groupId>
          <artifactId>ant-jsch</artifactId>
          <version>1.6.5</version>
        </dependency>
      </dependencies>
    </plugin>
    <!-- =========================================== -->
    <!--   antrun plugin end                         -->
    <!-- =========================================== -->
  
  </plugins>
</build>

This looks long, but don't be panic. To use it you need to change some properties for <scp> part.

localFile is the src file, remoteToFile is the dest file. You also need to change the authentication information like where you private key file is by keyfile, if you use public/private key for authentication, or just set the password for ssh.

Also you can use antrun to copy created jar to other dir on local file system by replace remoteToFile to localToFile.

Also remember to put you antrun plugin after other package plugin to make sure the jar file is already created when reach antrun. It's safe to put it at the end of the plugin list.

Let's run 'mvn  package', the output looks like below.

image

2. See also

Wednesday, January 27, 2016

Optimize static import assist in Eclipse

In order to make eclipse can auto-import Static methods, we need to make a little config in Eclipse. This article shows how to make the config in Eclipse to make auto-import for static methos works. Also this article list some classes you may need to set in Eclipse useful for your real projects.

1. How to setup content assist for static import in Eclipse

For example, although JUnit is in the classpath, by default eclipse can not give any help to import static method like assertEqual, which is a static method of class org.junit.Assert, see the screenshot below:

image

To make content assist works for static methods in Eclipse, you need to add the class which contain this static method to Eclipse, which in this demo is class org.junit.Assert.  First open menu "Windows ->  Preference".

image

image

Then, from left, find "Java -> Editor -> Content Assist -> Favorites". The word "Type" on the right may be misleading. it actually means the class that contain the static method.

image

Click Ok until finish. Now press "ctrl + 1", the content assist can give you helpful import suggestions like below:

image

2. Some useful classes for static import

Besides the org.junit.Assert in the previous example, here are more you may need in real development.

JUnit
  • org.junit.Assert
hamcrest
  • org.hamcrest.MatcherAssert
  • org.hamcrest.Matchers
Mockito
  • org.mockito.Mockito
PowerMock
  • org.powermock.reflect.Whitebox
Spring MVC test
  • org.springframework.test.web.servlet.request.MockMvcRequestBuilders
  • org.springframework.test.web.servlet.result.MockMvcResultHandlers
  • org.springframework.test.web.servlet.result.MockMvcResultMatchers
  • org.springframework.test.web.servlet.setup.MockMvcBuilders

Sunday, January 24, 2016

Break down package java.util.stream

Stream processing is significant feature of Java 8. In api level, it falls into package java.util.stream. By breaking down the package, you can get a whole view of how the stream api works.

Steam introduces map-reduce similar functions to Java. The article is based on Java 8.

1. Hierarchy
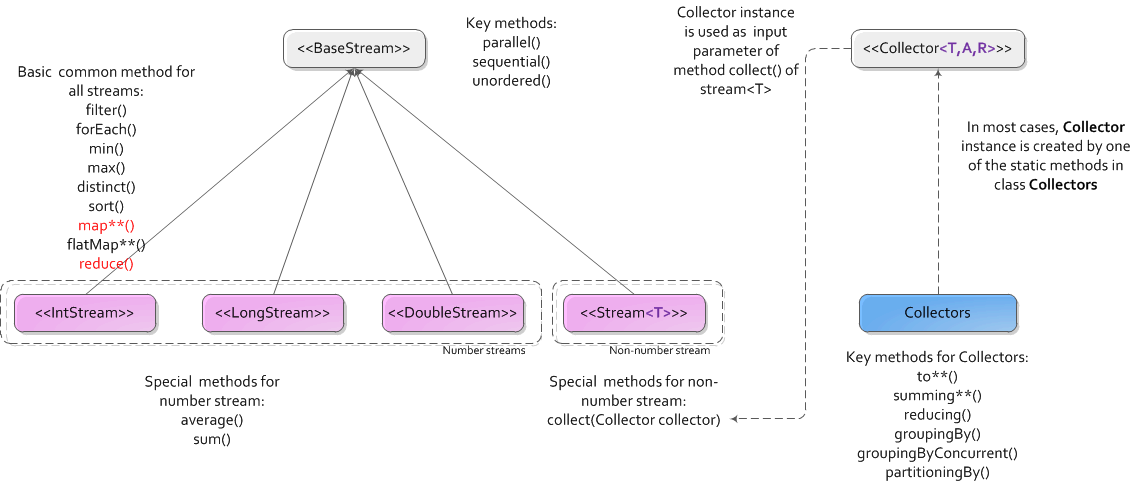
java_util_stream

The above only has most important components for understanding package java.util.stream.  4 builder interfaces corresponding to different stream type and 1 class for low-level library writers are not included.

There are only 1 class on above diagram, class Collectors, The rests are all interfaces. The most important are the 4 stream interfaces in pink. They can again be divided into 2 groups, streams for numbers and stream for other non-number object.  You can roughly think streams for number, IntStream/LongStream/DoubleStream, are special cases for Stream<T>, by set Generic Type T to Integer/Long/Double and add special methods for number manipulation like average(), sum().

All 4 streams has collect(supplier, accumulator, combiner) method. (supplier,accumlator,combiner will be described below). Method collect() provides the most general way to finally do the reduce. For number streams, in most cases, we don't need to use collect() at all, JDK provides shortcut methods, like average(),sum(),max(),min(), are good enough.

To simplify the usage of collect(supplier, accumulator, combiner) method, JDK extracts supplier, accumulator, combiner, together with finisher to the  interface Collector<T,A,R>. So reasonably there's an overload method collect(Collector<? super T,A,R> collector).

Furthemore, to make  collect(Collector<? super T,A,R> collector) easy to use, JDK provides the helper class Collectors with a bunch of static methods to create instance of Collector as input argument.

From the above diagram, we can see there's also reduce() methods for all stream, you can think them like simplified version of collect().

2. Stream methods

2.1 BaseStream functions

unordered(), make or just mark a stream is unordered. Usually it's used for parallel processing the stream. For example you have a stream from a list, which is ordered, but you only want to calculate the sum which has nothing to do with the order information, you can unordered the stream to make it can be processed in parallel.

sequential()/parallel(), change the stream to sequential or parallel.  Default stream is sequential for most cases, like the stream() return from a java collection.

2.2 Most used stream functions

For all example codes, suppose we have a variable users as list of User and  a stream userStream created from the list.

public class User {
  public static enum Gender {
    MALE, FEMALE
  }
 
  private Gender gender;
  private int age;
  private String username;
  
  // ignore getter,setter
}

List <User>  users;
// ignore initilization of users
Stream<User> userStream = users.stream();

filter(), screen out some element in the stream. For example

userStream.filtere(User u –> u.getAge() >= 18) //return stream with only adult users

will return a new stream with only adult users.

map(), can let you apply a given function on every element of the stream and create a new stream from that. For example

userStream().map(u->u.getAge());       //return Stream<Integer>
userStream().mapToInt(u->u.getAge());  //return IntStream

mapToInt() return a new IntStream which is convinient to process int elements.  There are also methods start with flatMap such as flatMap(),flatMapToInit(). The difference between map and flatMap is: map return only one output element for every one input element(Let's call it One-To-One), flatMap return multiple output for every single input(Let's call it One-To-Many).  for example:  

List&lg;string> lines = Arrays.asList("1 2 3 4", "5 6 7","8 9");
// every input string return multiple numbers
lines.stream().flatMap(line -> Arrays.asList(line.split("\\s+")).stream());

reduce(), will make a stream of type T finally return a single result of type T(let's call it Many-To-One). For example calcalate the sum of all users' age:

Optional<Integer> sum = userStream.map(u->u.getAge()).reduce((x,y)->x+y);
System.out.println("sum = "+sum.get());

When do reduce() on a Stream<Integer> return from map(), logically it will finally return a single Integer. In API level, a java.util.Optional<Integer> is used to contain that Integer.

Number streams has more methods special for number calculations, such as sum() or average(), so the previous example to calculate age sum can also be written like below:

int sum = stream.mapToInt(u->u.getAge()).sum();
System.out.println("sum = "+sum);

Also if we use the most generic method for reduction collect(), the previous age sum calculation can also be written like this:

int sum = userStream.collect(Collectors.summingInt(u -> u.getAge()));
System.out.println("sum = " + sum);

3. Collectors methods

The main purpose of class Collectors is to create Collector instance as input argument of stream's collect() method just like previous example. 

As name indicates, summing**() methods return Collector instance for producing the sum, averaging**() methods return Collector instance for producing arithmetic average. Here "**" can be Int, Long, and Double.

Methods like to**(), will return Collector that will return element in stream to a Java collection. Here "**" can be List, Set, Map,ConcurrentMap. The following example remove duplications from a list.

List<Integer> ages = Arrays.asList(25, 25, 30, 30, 35);  // list with duplication
List<Integer> distinctAges = ages.stream().distinct().collect(Collectors.toList()); // list without dup
System.out.println("distinctAges = " + Arrays.toString(distinctAges.toArray())); // [25,30,35]

Methods start like groupingBy() are very helpful.  They provide functions similar to "group by" in SQL.  There are several overload of groupingBy(), but mandatory parameter is the key to group, which will also be the key of the return Map.  For example, get a map of user grouped by gender, the key in the return Map is gender, the value is a user list of that gender.

// group users by gender
Map<Gender,List<User>> usersByGender = usreStream.collect(Collectors.groupingBy(u->u.getGender()));

If you want to calculate average user age for male and female respectively, see below.

Map<Gender, Double> averageAgeByGender = stream.collect(Collectors.groupingBy(User::getGender,
    Collectors.averagingDouble(User::getAge))); 
// print out  
averageAgeByGender.forEach((k,v)->System.out.printf("Average age of Gender %s is %f\n",k,v));

Methods partitioningBy(), can only group into 2 groups,  and key fixed to TRUE/FALSE,  so it can be thought as a simplified version of groupingBy(). 

4. Understand Collector

JDK provides class Collectors to make create Collector instance easily, so usually you don't play with Collector interface directly. But to better understand the stream process, you need at least know what a collector really does. 

Interface Collector<T,A,R> has 3 generic types:

  • T - the type of input elements to the reduction operation
  • A - the intermedia type of partial reduce result, most of time it's same as T, but as a application developer normally we don't care, so most of time "?" is used.
  • R - the result type of the reduction operation

The type T and R are more important for developers.

A collector has 4 main methods, they will be called internally in the collect() process. These 4 methods are:

  • creation of a new result container (A container = supplier().get())
  • incorporating a new data element into a result container (accumulator().accept(container, everyElement))
  • combining two result containers into one (combiner().apply(partialContainer1, partialContainer2))
  • performing an optional final transform on the container (finisher().apply(container))

The collector interface also provide a static method of(Supplier<A> supplier, BiConsumer<A,T> accumulator, BinaryOperator<A> combiner, Function<A,R> finisher, Collector.Characteristics... characteristics) to let you fully controll how to create a instance of your own collector.  Here's a example of creating Collector instance equivalent to Collectors.summingInt(), pay attention to how the supplier,accumulator,combiner and finisher are implemented.

// Can also defined as Collector<User,int[],Integer>
  Collector<User,?,Integer> myCollector; 
  
//myCollector = Collectors.summingInt(u->u.getAge());
  myCollector = Collector.of(
        () -> new int[1],                           //supplier
        (a, t) -> a[0] += t.getAge(),               //accumulator
        (a1, a2) -> {a1[0] += a2[0];return a1;},    //combiner
        a -> a[0]);                                 //finisher
    
  int sum = userStream.collect(myCollector);
  System.out.println("sum = " + sum);

5. Recap

To understand Java stream processing, we need to understand 4 stream interfaces(Stream<T>,IntStream,LongStream and DoubleStream), 1 Collecor interface and 1 Collectors class. Stream provide operations on every element in the stream, then reduce the element to final result. Besides many out-of-box functions for reduction, you can also use Collector and Collectors for more generic reduction operation.

Monday, January 18, 2016

Method Reference in Java 8

In java 8 method reference is introduced as a helper for the outstanding feature, Lambda Expression.  In some cases a lambda expression does nothing but to call an exsting method.  Method reference let you make this kind of lambda expression cleaner and shorter.

Let see an example, suppose we have a stream created from a User list. The class User has a int field call age with getter and setter.

List<User> users = Arrays.
//... add user in to list
Stream<User> stream = users.stream();

First without using method reference to calculate the averge age of all users.

Double averageAgeDouble = stream.collect(Collectors.averagingDouble((User u)->u.getAge()));

Using method reference, it looks like below

Double averageAgeDouble = stream.collect(Collectors.averagingDouble(User::getAge));

The method reference is shorter than normal lambda expression. The syntax is className::methodName,  which in our case is User::getAge, means arbitrary object of class User and the method name is getAge().

Thursday, January 7, 2016

Why DAO or Respository bean can be singleton in Spring

This question based on one fact: instance of javax.persistence.EntityManager is NOT thread-safe. Then how does spring handle concurrency on singleton DAO object.

Suppose we have a simple DAO bean  looks like below, used in a concurrent scenario, such as in a web application.

import javax.persistence.EntityManager;
import javax.persistence.PersistenceContext;
import javax.transaction.Transactional;

import com.shengwang.demo.model.User;  // a trivial entity

@Transactional
public class UserDao {
  @PersistenceContext
  private EntityManager em;
  
  public void addUser (User user) {
    em.persist(user);
  }
}

Can you set the scope of this bean to singleton in JEE context?  (NO)

Can you set the scope of this bean to singleton in Spring context? (YES, but why? see below)

1. In JEE

Usually DAO bean is stateless. Our DAO bean above is just a stateless bean, so in JEE most common way is to mark it as @Stateless and create a instance pool of this DAO. JEE container will maintain this pool,  assign a  bean instance handle for every individual invocation, and bean will release back to the pool after invocation.

Because the EntityManager is non thread-safe, the solution for concurrency in JEE is creating a pool.  That sounds reasonable.

2. In Spring

The default scope of bean in spring is singleton, and offical document recommend you to set DAO bean singleton, which means just use the default scope config is fine.

But Why? When multiple threads access this single object, why the non thread-safe EntityManager instance does not complain? The reason is  that in Spring framework, the Entitymanager instance em in the Dao bean is not a real EntityManager, but a proxy.  Which mean very invocation on em, like em.persist(), is handled by a  proxy.

In case you are not familiar with Proxy in Java reflection, here are  some basic knowledge for quick understanding.

2.1 basic about proxy

In java reflection package java.lang.reflect , there is a Proxy class.  Java provide a mechenism to create a proxy for any class.  Suppose we want to create a proxy for class Foo. Code looks like :

Foo f = (Foo) Proxy.newProxyInstance(Foo.class.getClassLoader(), new Class[] { Foo.class }, handler);

The instance f is a proxy. The last parameter handler is an implementation of interface java.lang.reflect.InvocationHandler. When any methods of instance f get called, the handler’s only method , invoke(Object proxy, Method method, Object[] args), get called. So in this method,  you have a chance to place some logic before/after the real invocation.

2.2 Spring use proxy to get real EntityManager on every invocation.

Since the em injected to DAO is just a proxy, every call on the em will first try to get the real EntityManager object in the handler.  This logic is located in org.springframework.org.jpa.SharedEntityManagerCreator. This class implements the InvocationHandler interface and has a invoke() method. In this method, there are codes like:

EntityManager target = EntityManagerFactoryUtils.doGetTransactionalEntityManager(...);

This doGetTransactionalEntityManager(…) will get EntityManager bound to current thread! If we follow the doGetTransactionalEntityManager(…) method, we will find following in method.

EntityManagerHolder emHolder = (EntityManagerHolder) TransactionSynchronizationManager.getResource(emf);

Keep tracking getResource(…), you will found the resource is a ThreadLocal map variable defined in class org.springframework.transaction.support.TransactionSynchronizationManager

Now you should understand why the Dao can (should) be a singleton bean in spring framework. Because spring internally use Proxy and ThreadLocal to eliminate the impact the non thread-safe EntityManager bring to stateless bean.  No need to create pool for concurrency anymore!

All code snippets above are based on Spring framework 4.1.0.RELEASE.

3. Recap

To some extends, you can think spring framework use a ThreadLocal variable as the stateless bean pool in JEE. You can also think this somehow way of a Flyweight design pattern, use a shared object to save overhead of create/destroy objects.

Powered by Blogger.

About The Author

My Photo
Has been a senior software developer, project manager for 10+ years. Dedicate himself to Alcatel-Lucent and China Telecom for delivering software solutions.

Pages

Unordered List